• Services
    • Data Analysis
    • Data Engineering
    • Data Visualisation
    • Data Science
    • Data Consulting
    • Software Engineering
  • Industries
    • Manufacturing
    • Real Estate
    • Marketing
    • Retail
    • Logistics
    • Healthcare
    • Automotive
    • Financial Services
  • Resources
    • Portfolio
    • Dashboards
    • Blog
  • About Us
  • Careers
  • Contact Us
  • Services
    • Data Analysis
    • Data Engineering
    • Data Visualisation
    • Data Science
    • Data Consulting
    • Software Engineering
  • Industries
    • Manufacturing
    • Real Estate
    • Marketing
    • Retail
    • Logistics
    • Healthcare
    • Automotive
    • Financial Services
  • Resources
    • Portfolio
    • Dashboards
    • Blog
  • About Us
  • Careers
  • Contact Us

Customer Churn Analysis

  • April 24, 2026
  • •

A 5% increase in customer retention can boost profits by 25–95% — yet most churn remains unaddressed.

What is customer churn, and why is it important to take it into consideration? The sooner, the better. In the early phase of a company, the focus is usually on attracting and acquiring new customers rather than retaining the existing customer base. This is totally fine at this stage, but sooner than expected, as the market is not unlimited, the company reaches the point when acquiring one customer costs more than retaining one. Retention is sometimes cheaper, more predictable, and can generate higher long-term value than continuously acquiring new customers. Ideally, companies should start analyzing customer retention opportunities and the drivers of churn from the very beginning. 

How do we define the churn?

Before starting any complex calculation, it’s important to precisely define how we classify a churned customer. 

In sectors like insurance and banking, it’s easier, because as long as we have a contract, the customer is active, and once they step back from the contract, they are considered a churned customer. It is important to keep in mind that customers whom we terminated should not be labeled as churned, as the reason why we cancel a contract is probably different from their reasons. Classifying them as churned would reduce the accuracy and reliability of our predictive churn model. 

In sectors like retail, the definition of churn is not self-explanatory. We should determine the exact definition of churn and modify it later if necessary. For example, in a retail webshop: what is a churned customer? Those who haven’t placed an order in 6, 12, or 24 months? To determine this, we also need to check the so-called returning probability after n months of inactivity. As a result, we get a table where we can see that after n months of inactivity, the probability that the customer never returns is p. 

Month of inactivity 

Churn probability 

1 

0.12 

3 

0.28 

6 

0.45 

12 

0.9 

24 

0.98 


We should select the exact churn definition based on this result and follow or adjust it if needed. 

Once we have the definition of a churned customer, we should start calculating the financial impact of such an event. In simple terms, it means estimating the average loss on a randomly selected customer. 

This should not be a complicated calculation. We can take the average monthly or yearly spending of a customer, and this will represent the amount we lose if a randomly selected customer decides not to choose our service or product anymore. 

It is worth segmenting customers into categories across different axes such as age, geographical location, gender, etc., and calculating this average per group. This way, we get a more detailed picture of how average spending differs across segments. For example, younger customers might spend less per month but be more active, while customers from a certain region might generate higher revenue. 

If we multiply the average spending by the size of each segment, we can estimate the total value of that group. Combining this with the churn rate, we can also estimate the financial impact of customer loss within each segment. 

If the company has a well-structured marketing team, they likely have precise numbers showing the cost of acquiring a new customer. This allows us to compare acquisition cost with the loss caused by churn on an individual level. 

It is never an optimal strategy to spend all resources on acquisition while there is a significant leakage on the other side. A balanced approach between acquisition and retention is key. 

What is the purpose of using ML models?

So far, this is not the reinvention of the wheel; probably every company has a similar calculation. So why do we need ML models and advanced statistics for churn prevention? 

Because without ML models, churn is only an event. At a certain point, a customer decides to leave, and we have no tools in our hands to do anything about it. We can only see what happened in the past and evaluate it, but it does not provide a data-driven approach to detect which customers are likely to leave in the future. 

ML models, on the other hand, analyze historical data and try to find recurring patterns in customer behavior that led to churn. This, however, is only the first part of the task. Once these patterns are identified, the model applies them to the current customer base and provides signals like: 

“Based on the common behavior patterns of customers who left, these are the customers in the current base who behave similarly, indicating that they are likely to churn in the near future.” 

And this is exactly what a company needs: signals or early warnings that identify potential leavers, so proactive retention actions can be taken. 
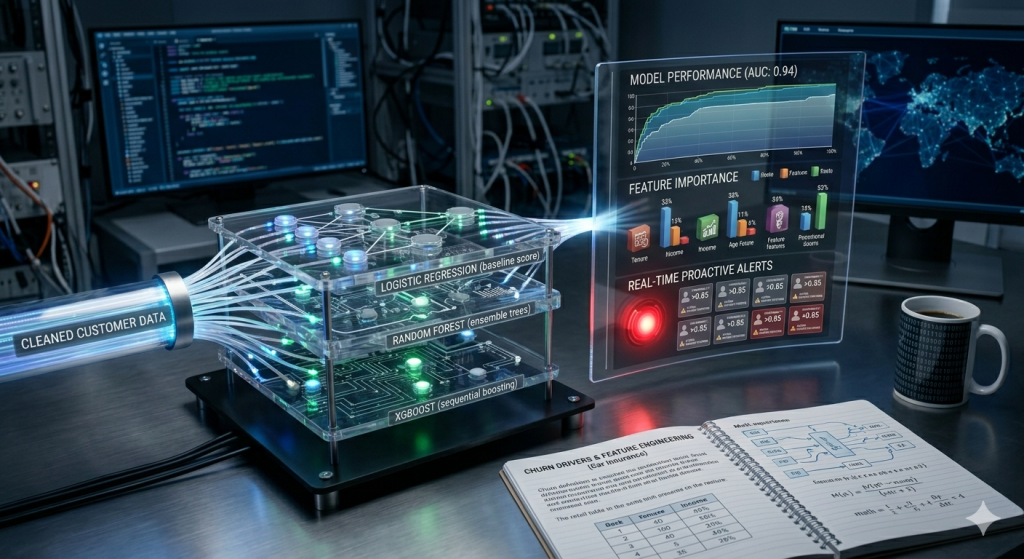
How do ML models work in churn analytics, and which models are commonly used? 

  1. Feature selection – understanding what drives churn 
    First, we analyze the characteristics and behavior of each customer: age, geographical location, income, usage patterns, and everything available to us. Our goal is to identify which variables have an impact on the target event: whether the customer leaves (churn = 1) or stays (churn = 0). 

At this stage, we focus on identifying relevant features, meaning the variables that potentially influence churn. The exact combination of features is not fixed; it is recommended to test different combinations and refine them iteratively. 

  1. Model building – learning patterns from historical data 
    Once we have selected the features, we build an ML model that learns from historical data. The model identifies patterns and relationships between customer behavior and churn, and uses these patterns to predict the likelihood of churn for current customers. 
  1. Commonly used models in churn analytics 
  1. Logistic Regression
    A simple and widely used model. It assigns weights to each feature and combines them into a score between 0 and 1, which represents the probability that a customer will churn. It is easy to interpret and useful as a baseline model.
  2. Random Forest
    An ensemble model that builds multiple decision trees and combines their results. Each tree captures different patterns in the data, and together they provide a more robust and accurate prediction, especially when relationships are complex.
  3. XGBoost
    A more advanced boosting algorithm that builds trees sequentially, where each new tree focuses on correcting the errors of the previous ones. It is often one of the best-performing models in churn prediction tasks.

It is important to note that the model itself does not make business decisions. It does not know the cost of retention or the value of a customer. It only provides a probability. The final decision always belongs to the business. 

How to evaluate and use the results in a business context 

Example: 

  • Average cost of retaining a customer (e.g., campaign, discount): 50 USD 
  • Average customer value: 200 USD 

Case 1: High churn probability 
If the churn probability is 0.9, the expected loss is: 
0.9 × 200 = 180 USD 

If we spend 50 USD on retention and reduce the churn probability to 0.2: 
0.2 × 200 = 40 USD 

The reduction in expected loss is: 
180 − 40 = 140 USD 

Since we spent 50 USD to save 140 USD, the intervention is clearly profitable. 

Case 2: Lower churn probability 
If the initial churn probability is 0.4: 
0.4 × 200 = 80 USD 

After the campaign (reducing it to 0.2): 
0.2 × 200 = 40 USD 

The reduction in expected loss is: 
80 − 40 = 40 USD 

Here, we spent 50 USD to save 40 USD, which means the intervention is not profitable. 

Conclusion 
ML models help us identify who is likely to leave, but the real value comes from combining these predictions with business metrics. The goal is not only to predict churn, but to take actions where the expected benefit is higher than the cost. 

How does this look life in a real life example?

In practice, both the data and the ML model usually run in a database or a data platform that decision-makers do not directly access, and the results are not easily interpretable in raw form. Therefore, tracking and understanding the results should happen through a well-structured dashboard. 

In the following example, we built a customer churn analytics dashboard based on car insurance data. 


Understanding the data and business context 
We worked with a car insurance dataset, where the definition of a customer churn is straightforward: anyone with an active contract is considered an active customer, and those who terminate their contract are considered churned. 

The dataset includes both descriptive attributes (such as age, income category, home value, number of properties owned) and behavioral data (such as contract start date, contract value, and tenure, meaning how long the customer has been with us). 

From data to insights 
After selecting the relevant features, we analyzed their impact on the customer’s decision to stay or leave. One of the key findings confirmed an intuitive assumption: the longer a customer stays with the company, the lower the probability of churn. 

This is a strong business insight. It suggests that the first period of the customer lifecycle is critical, and retention efforts should focus on the early stage of the relationship. If a customer does not churn early, they are significantly more likely to stay in the long term. 

In addition, factors such as income and age also showed a meaningful impact on churn. At the same time, geographical variables turned out to be much less relevant, indicating that segmentation based on location would not provide significant business value in this case. 

From raw data to business decisions 
Looking only at churn rates can be misleading. A segment might show a high churn rate, but if the number of customers in that segment is small, the overall financial impact is limited. 

For this reason, the dashboard not only shows rates but also provides context by displaying the size of each segment. This allows the user to immediately understand how many customers belong to each category and which segments require the most attention from a business perspective. 

Turning insights into action 
On the next page of the dashboard, we focus on the most important business metrics, such as the expected financial loss per segment. The dashboard also allows users to drill down to individual records and further break down segments into subcategories. 

This enables marketing and business teams to identify high-value, high-risk customer groups and design more targeted and efficient retention campaigns. 

Overall, the goal is not only to analyze churn, but to translate data into clear, actionable insights that directly support business decisions. 

Share this post

Squery: Unparalleled IT solutions, data consulting, and business analytics.

Linkedin Facebook Instagram Twitter
Services
  • Data Visualisation
  • Data Analysis
  • Data Engineering
  • Data Science
  • Data Consulting
  • Software Engineering
Quick Links
  • About Us
  • Portfolio
  • Blog
  • Careers
  • Terms of Service
  • GDPR
  • FAQ
  • About Us
  • Portfolio
  • Blog
  • Careers
  • Terms of Service
  • GDPR
  • FAQ
Get In Touch
Contact Us

info@squerysolutions.com

+36 30 496 2489

Monday to Friday 9:00 AM - 5:00 PM